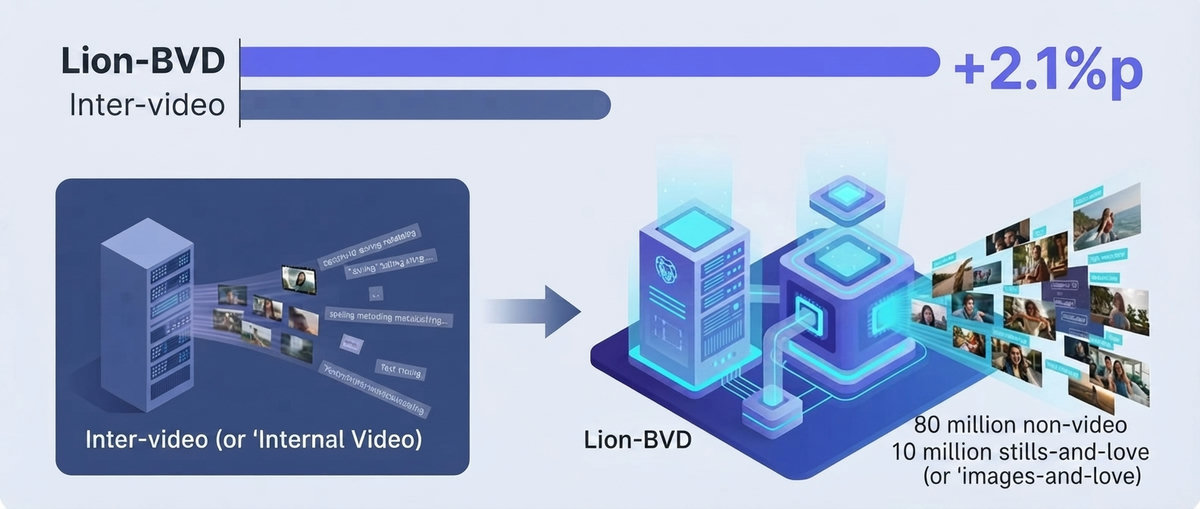
LAION, a non-profit artificial intelligence research organization, has released LAION-BVD, a massive open video dataset totaling 10 million hours for multimodal artificial intelligence research. This dataset was built by actually downloading 80 million videos based on 1.3 billion video URLs collected from Common Crawl. Models trained on this dataset achieved up to a 2.1 percentage point improvement in video-text evaluation performance compared to the existing video benchmark InternVid.
Until now, large-scale video datasets and the models trained using them have largely been the exclusive domain of a few proprietary companies, limiting independent scientific research and reproducibility. LAION built this dataset to break this technological monopoly and support open, reproducible multimodal research. Regarding copyright issues, LAION distributes the dataset strictly for academic research purposes, based on a 2024 ruling by the Hamburg District Court in Germany that permits the collection of copyrighted works for non-commercial research purposes.
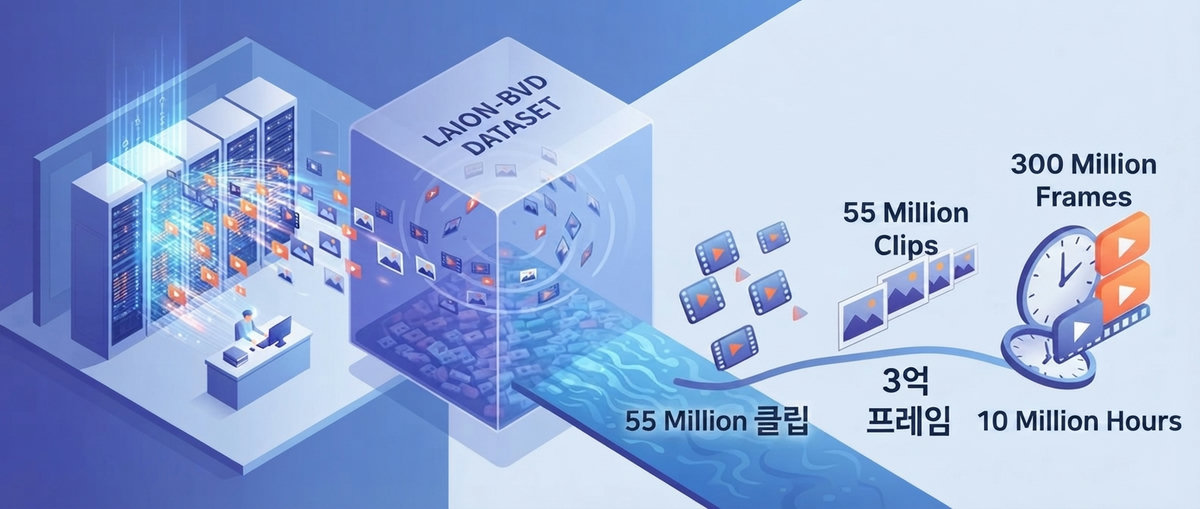
LAION-BVD includes 55 million caption clips with automatically generated video and audio descriptions, as well as 300 million image frames extracted at scene transition points. Detailed descriptive annotations for each clip were automatically generated using a 2-billion-parameter model. The dataset and its associated open-source code are available for free on Hugging Face and GitHub for researchers worldwide to use immediately.
Since LAION-BVD is a machine learning dataset rather than a generative AI model that directly creates video or audio, it cannot be run and used within the 5HOW.ME editor at present. However, this dataset provides an academic foundation for the open-source community to train advanced multimodal AI models spanning video, audio, and image domains. This directly contributes to accelerating the development of open-source video AI technologies by independent researchers in response to proprietary companies.
참고